AI NewsProductivityAnnouncement
Nitin Garg found a written spec left code reviewers' bug-catch rate unchanged
Nitin Garg's within-subject study of five reviewers on two AI-generated banking services measured 81 percent finding-to-requirement attribution with a written specification against 0 percent without it, at a cost of 21 minutes per review, with no change in the recall rate.
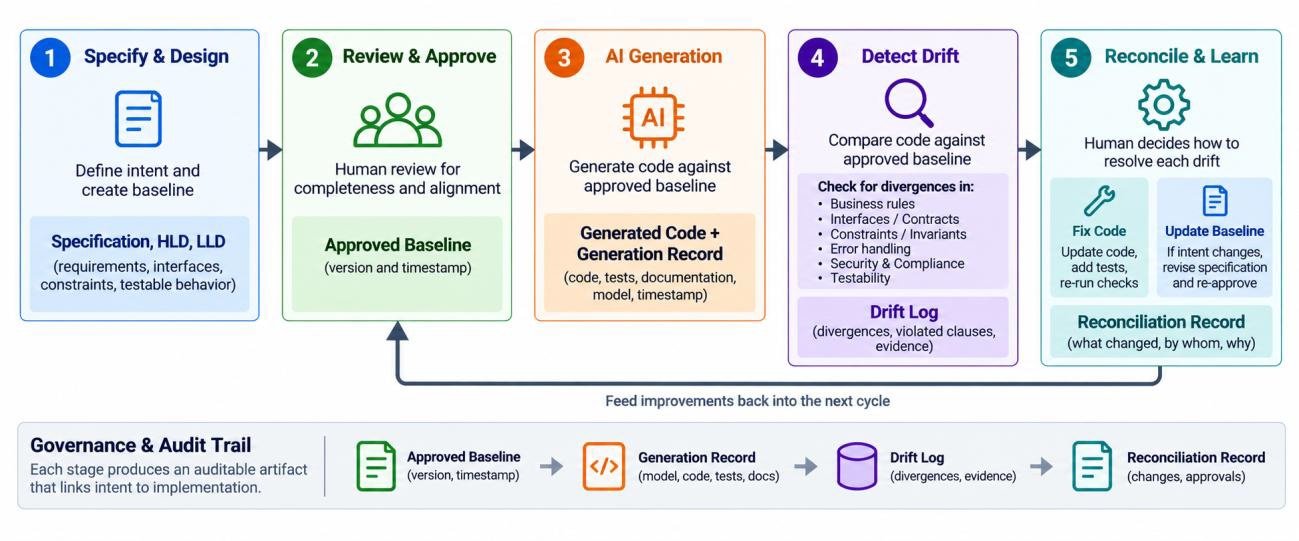
Image: Nitin Garg, InfoQ
Why it mattersThe payoff of spec-driven review is a traceable audit trail for regulated work, so the case for it depends on whether the trail is worth 21 extra minutes per review at the same catch rate.
Nitin Garg published a study on InfoQ on 2026-09-10, accepted at GAISS 2026, on whether writing a specification before generating code with an AI model changes what a human reviewer finds. Five reviewers with 3 to 10 years of experience each reviewed two AI-generated banking services under two conditions: code with a specification baseline, and code alone. The paper is labelled preliminary and only a general indication, with small samples.
What the numbers actually say
Garg says the two services carried 11 and 10 adjudicated defects, seeded and unintentional. Recall stayed the same: 0.525 with the specification baseline against 0.518 with code only, p equal to 0.69. Attribution rose: 81 percent of findings were tied to a named requirement when the baseline was present, against 0 percent without it, p equal to 0.043. Review time went from 27 minutes on code alone to 48 minutes with the baseline, an extra 21.7 minutes per review at the same p value.
Garg also ran 90 machine reviews across Anthropic Claude Opus 4.8, OpenAI GPT-5.2, DeepSeek V4 and Google Gemini 3.1 to check that the pattern was not a quirk of the human sample. He reports that the same pattern held: no recall gain, a real attribution gain.
The generation part of the study
The paper covers generation as well as review. Garg reports that a staged approach that produces a specification first and then code from it reached a 45 percent pass rate on his banking tasks, against 23.8 percent for direct generation from the same prompt. That is a bigger difference than anything in the review numbers, and it is where Garg sees the main benefit of a written specification: hard, multi-constraint work built by a capable-but-imperfect model.
Where the benefit actually is
Adding a specification to the reviewer's screen did not help them catch more bugs. Garg says the sample is small, and the p value on recall is 0.69. Every finding could be linked to a written requirement rather than to a reviewer's private judgement. In regulated software that is the point of the exercise: the auditor asks which requirement a defect breaks, and the answer is no longer "the reviewer thought so".
The 21 extra minutes per review is the price. On a service with 10 or 11 defects that works out to 2.07 minutes of extra reviewer time per defect that can now be cited to a requirement rather than to intuition. In finance, health and other domains where audits will happen, that is a trade a team will take. On a script that nobody will audit, the same 21 minutes gives nothing.
The other problem in the numbers is that the recall figure of 0.525 is already low: reviewers caught half the defects, with or without a specification. Garg reads this as evidence that the specification changes the vocabulary of the review while leaving its depth alone. The finding fits the pattern of the recall gap he measured, and it leaves the question of how to raise recall open.
Source
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.