AI NewsProductivityReported
Akka ran a spec-driven AI porting pass over 65 open-source projects and 57 of them came out faster or shorter
InfoQ reports Akka tested a spec-driven AI porting workflow on 65 open-source projects; 57 of the ports came out with fewer lines of code or better performance, at a cost of 9.41 billion tokens.
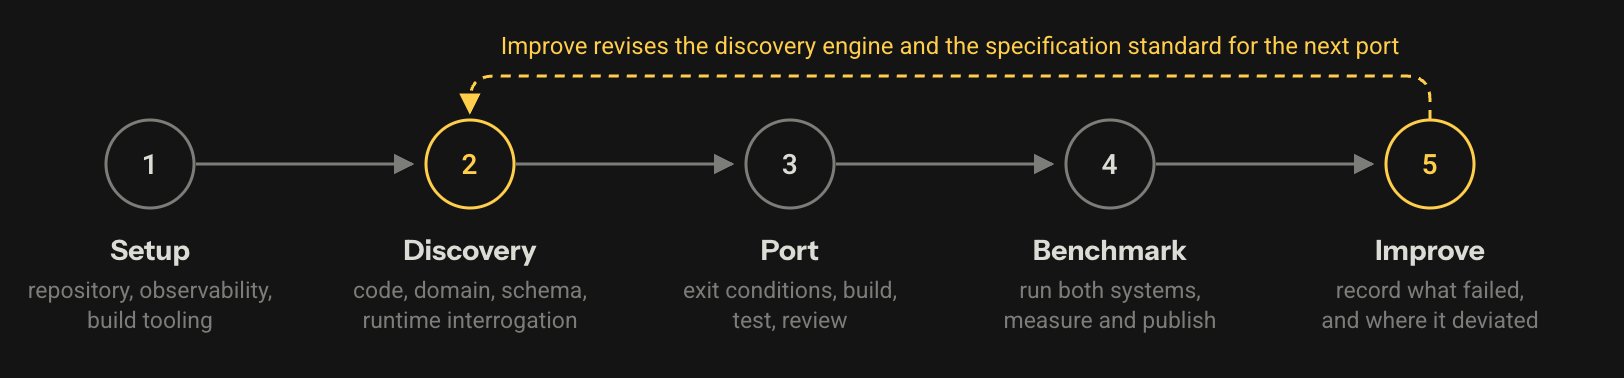
Image: InfoQ
Why it mattersA measured recipe for turning an AI porting job into a repeatable workflow gives a team numbers to argue over, instead of a sales deck claiming a general speed-up.
A team porting a library with AI usually has no idea whether it is winning.
InfoQ reports that Akka ran a spec-driven delivery experiment on 65 open-source projects, publishing the figures on 5 October 2026. Leela Kumili wrote the piece, drawing on Akka's blog post and a LinkedIn thread from Akka's CEO Tyler Jewell. Akka's own harness cycled every project through five phases: discovery, specification, porting, benchmarking and improvement, with Claude and Akka Specify doing the implementation, testing and review work from detailed specifications.
The numbers Akka reports
Across the initial tranche, the harness ran for 99.3 hours and used 9.41 billion tokens. 57 of 65 ports came out with either a drop in lines of code, a measurable performance improvement, or both. 10 of the 65 were taken all the way through to a complete implementation.
Two model-level results sit under that total. Claude Sonnet averaged 61 minutes per port. Claude Opus averaged 120 minutes but used about 40 percent fewer tokens. The post includes one outlier, a 143,333-times improvement for Dify, which Akka reports as its own measured figure.
Every one of these numbers is Akka's own measurement on its own workflow, and the harness is the one it sells. A buyer should read them as the vendor's best case, not a neutral benchmark.
Why spec-driven changes what the model does
The specification is the point of the method. The harness does not hand the model a repository and ask it to port the thing. It writes a specification that pairs claims about the current project with evidence and typed behaviour the port must preserve, then uses the specification as the test the port is scored against. Convergence happens in the benchmarking and improvement phases, where the model loops until the port passes the specification.
That is why 57 of 65 projects came out improved rather than merely finished. The specification carries the before-numbers; a port that preserves behaviour but adds a slow path cannot pass. It is also why the Sonnet-versus-Opus split is interesting beyond its hourly rate. Opus is slower per port but needs fewer tokens, which hints that the smaller model is spending more of its budget on retries that the bigger model avoids on the first pass. A team costing out an agentic workflow would want both numbers before picking.
The piece does not say which 65 projects were chosen, which languages they were in, or how the specification was authored. Those three details decide whether the method travels to another codebase or not; a buyer should ask Akka before trusting the headline.
Source
- Akka Tests Spec-Driven AI Delivery Across 65 Open Source Projects, InfoQ, 5 October 2026.
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.