AI NewsModels & agentsReported
Anthropic says Mythos got Claude running on AMD GPUs in three days
Anthropic says its Mythos model ported Claude to AMD GPUs in three days. The company says that job used to take six to twelve months.
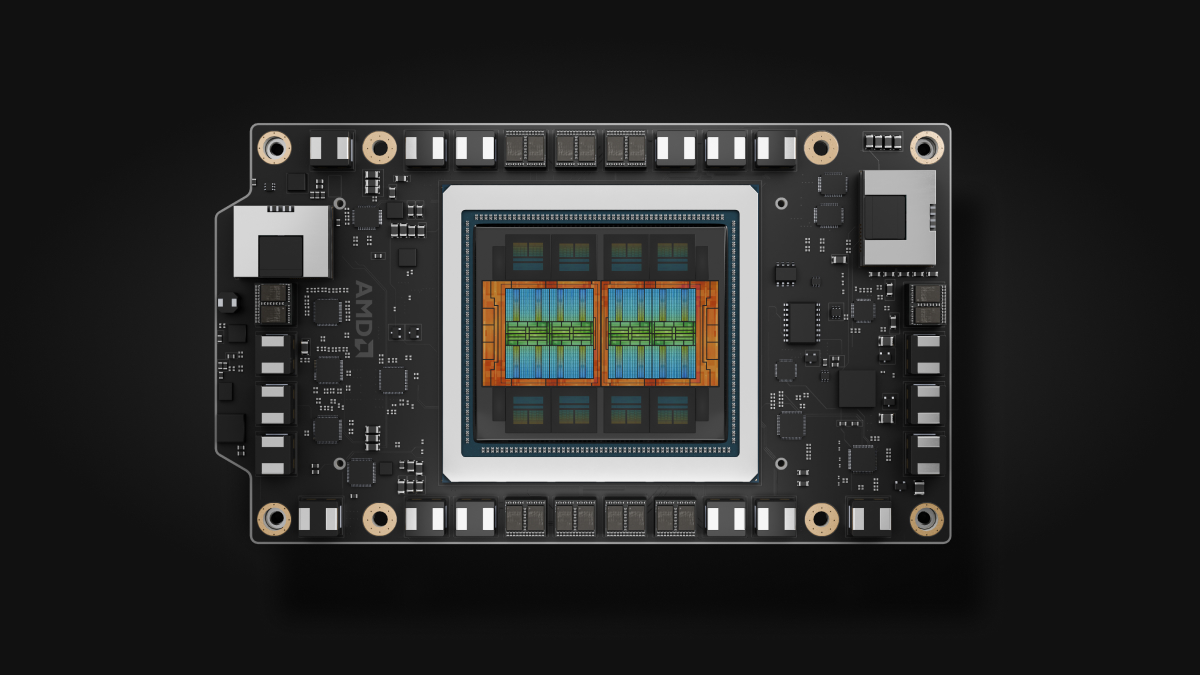
Image: Tom's Hardware / AMD
Why it mattersA team that cuts chip onboarding from months to days chooses a hardware vendor on cost alone. That is the first real crack in Nvidia's lock on model training.
A chip without software support is a paperweight. Running a big model on a new accelerator takes months of hand-tuned kernel work. Anthropic says its own model Mythos just did that work on its own. The job took three days, on AMD hardware.
Tom Brown is Anthropic's co-founder and chief compute officer. He made the claim in the company's IPO roadshow video on 10 November 2026. Tom's Hardware reported Brown's words on 16 November. Brown said Mythos got Claude running on AMD in just three days. He said this happened with basically no human intervention. Mythos also ported or wrote almost 100 percent of the kernels, Brown said.
What Anthropic says it did
Anthropic lists the scope in a footnote on its own slide, and the detail matters. The three days covered prompt processing. That is the step the model does when it reads the input before answering. It is one part of running a model, not all of it. The chip was AMD's MI355X, a single accelerator in AMD's Instinct series. The model was one Anthropic model, and the company has not named which one.
Brown's benchmark is Anthropic's own past: "dozens of engineers, months of work" to bring a new chip online. Anthropic puts that number at six to twelve months for an outside team. The company has not published the test, the kernel code, or an independent measurement.
Why Anthropic is saying it now
The IPO roadshow is Anthropic's pitch to investors, not a technical paper. Brown is talking to the people paying the compute bill. That bill runs through Nvidia. Nvidia has long had the better software side of the GPU story. AMD's hardware has often matched Nvidia's on paper. The reason training stays on Nvidia is CUDA. CUDA is Nvidia's software layer, with a decade of tuned kernels behind it.
If a frontier model can write the AMD-side kernels itself in days, that story weakens. A buyer with the choice would start comparing chips on dollars per token. Engineering time stops being the limit.
What a founder picking hardware should take from this
Anthropic has given itself a cheaper option, and it is telling its investors so. For anyone else, the claim is an announcement, not a benchmark. The kernels are not public. The MI355X is a large accelerator most teams will not buy directly. The performance gap between CUDA and the agent-written AMD code is not stated. That is the number that would change a purchase.
The point worth filing is the direction, not the figure. The compute bill at an AI company is the largest line on its balance sheet. A tool that swaps one GPU vendor for another in days is the first thing that can move that number. The story will be real when another team repeats the result on its own hardware. That team also has to say what the gap was.
Source
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.