Image: Amazon Web Services
Why it mattersA team with a price list or a product table no longer has to convert it to a search-friendly document. The agent reads the table as a table.
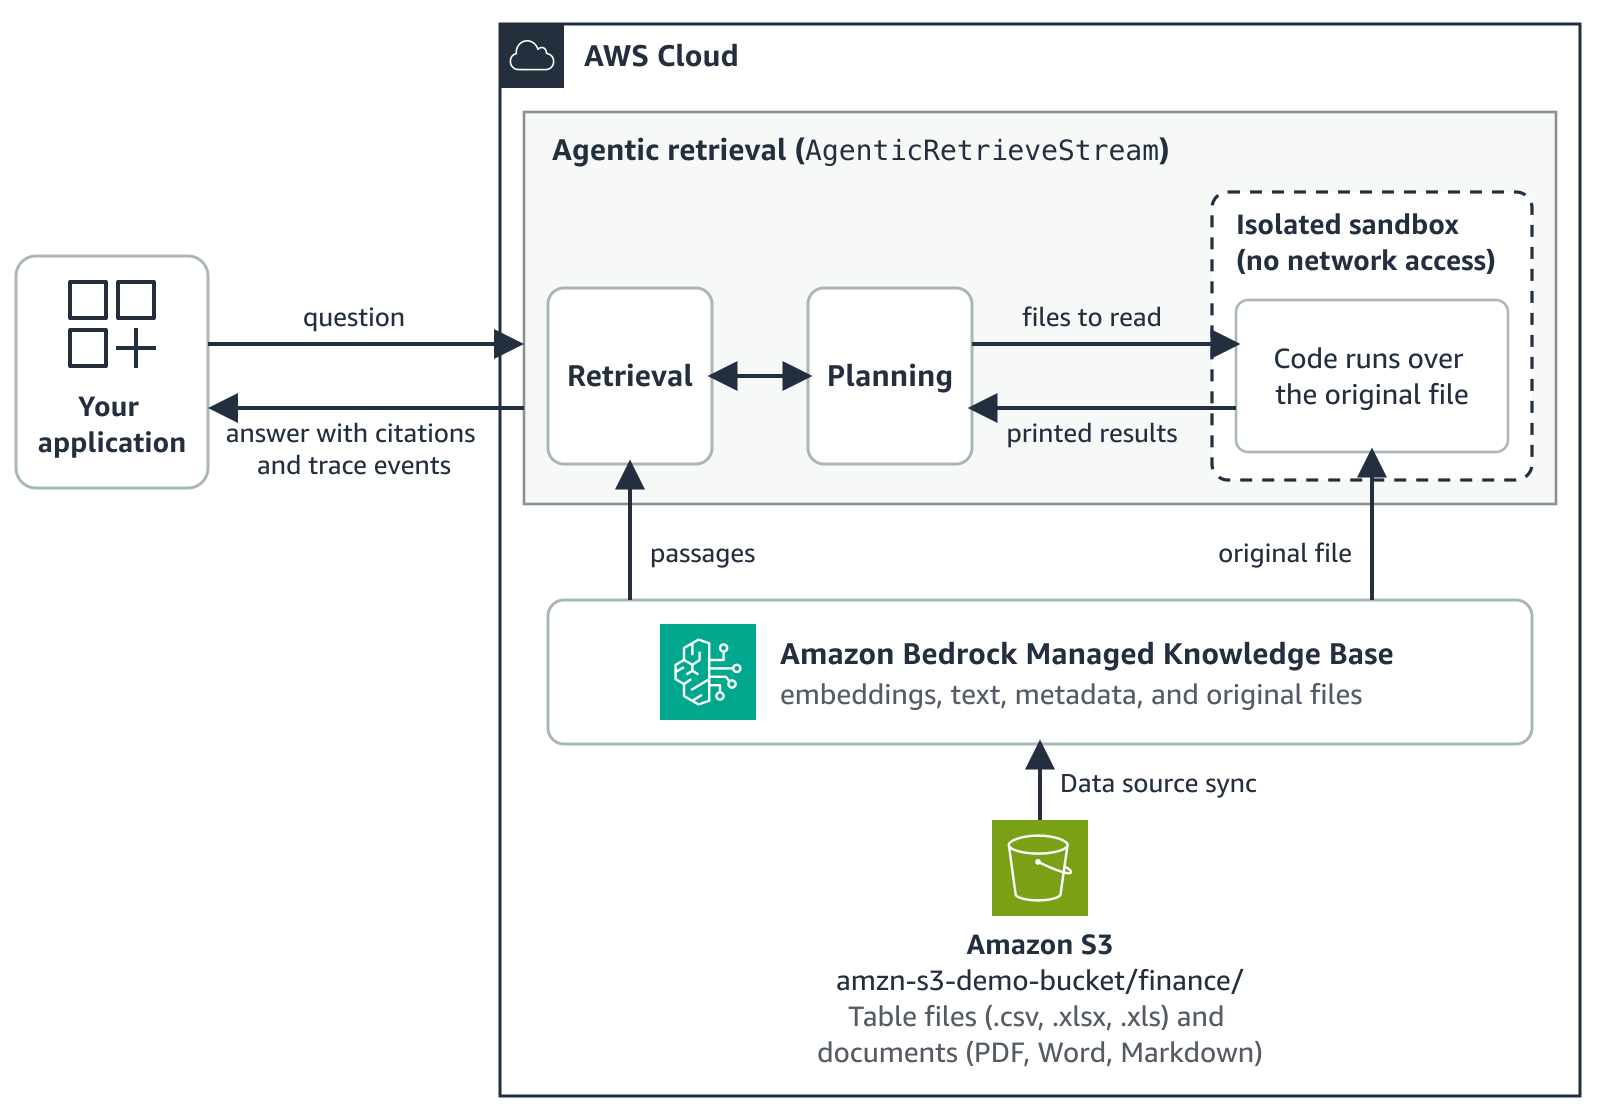
A team feeding a price sheet or a product catalogue to a retrieval system has had one option: turn every row into a text chunk and hope the search finds the rows it needs. Amazon Bedrock Managed Knowledge Base now reads the file as a table. An agent can run a small program over every row in one or more tables.
Amazon Web Services announced tabular search in Bedrock Managed Knowledge Base on 16 November. The post is on the AWS Machine Learning blog. The feature works with three file types: CSV, XLSX and XLS. The agent reaches it through the AgenticRetrieveStream API request.
What it does
The retrieval step for a tabular source does not pull back the matching chunks. It runs model-written code in a sandbox over the whole table or sheet. The AWS post says the code "runs over the whole table instead of only the rows that retrieval returns". The sandbox has no network access. The answer can also mix a table source and a document source in one request.
What an agent can now do that it could not before
The agent can look up a value in one row and use it in another. It can run calculations across every row. It can join a table with a text document in one call. A question that needs a number from the table and a sentence from a policy document is one call. A question can span more than one table or sheet in the same knowledge base.
AWS gives one example in the post. A health plan asks whether a member's coverage includes a procedure. The retrieval step finds the member in a CSV row, then checks the plan terms in a separate document. The answer is cited to both sources.
What it costs
AWS does not publish a tabular-search price in the post. The feature follows standard Amazon Bedrock rates, and pricing is on the main pricing page. The post says the extra step takes longer than a text-only answer. The agent runs a second turn to call the sandbox. AWS does not state a time range.
The feature is available in the AWS Regions that already support Managed Knowledge Base. Which regions those are varies by account.
For a team already using Bedrock
Load the CSV or Excel file into the knowledge base. The agent reads it as a table. A team with a spreadsheet of prices, discounts or specifications no longer has to flatten it into Markdown. A team with a long Excel export no longer has to add a search field for each column. The tool call is the same AgenticRetrieveStream, with no extra parameters to set.
Source
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.