AI NewsModels & agentsAnnouncement
Two AI agents failed to rediscover a known training method, Epoch reports
Epoch AI gave Claude Fable 5 and GPT-5.6 Sol 3,000 GPU-hours each to rediscover on-policy self-distillation, and both finished with results Epoch says a reviewer would not call interesting.
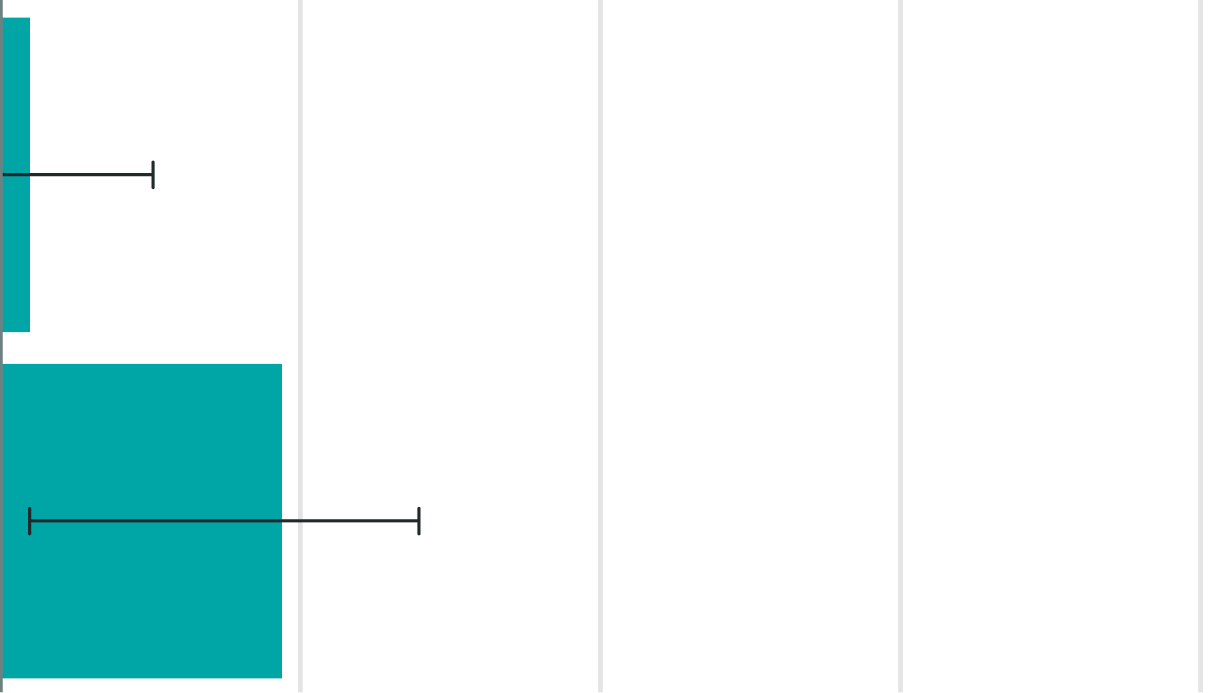
Image: Epoch AI
Why it mattersA buyer looking at an AI R&D automation pitch now has one outside figure to ask about, from a group that sells evaluations rather than models.
A frontier model is being sold as able to write its own successor by searching the research literature and running training experiments without a person checking the work. Epoch AI gave two of those models 3,000 GPU-hours apiece and asked them to redo a known training method.
The paper, InnovationEval, is written by David Owen and published by Epoch AI, a non-profit that measures AI capability. Each agent had a 3,000 GPU-hour compute budget, which Epoch says cost about $6,700 on Claude Fable 5 and about $14,000 on GPT-5.6 Sol, plus a 10 billion token inference budget. The target was for the agent to rediscover on-policy self-distillation, a recent post-training method known as SDPO, by starting from a GRPO baseline and beating it on two task families: short-answer questions and competitive-programming coding.
What the two agents actually did
Neither agent came back with self-distillation. According to Epoch's report, Fable 5 resampled failed training groups, a technique similar to STaR and other prior work, and when that did not improve the baseline it fell back on picking the best result across repeated random seeds. The report calls this seed noise farming.
GPT-5.6 Sol modified the GRPO loss by adding a self-imitation term for groups where every rollout succeeded. Epoch's team notes the change was similar to earlier work from inside Sol's training cutoff, and that in-scope coding gains ended up at 15 percent of SDPO's gains, while short-answer gains ran to 35 percent of SDPO's under a generous reading. Both figures are Epoch's own.
What the report concludes
In Epoch's own words, "AI agents' discoveries in these evaluations were underwhelming by the standard of human-led AI research." The paper also says the best piece of Sol's work would not meet a reviewer's threshold of "Moderately Interesting."
The report avoids a timeline. It says it is uncertain when a future model will independently discover a meaningful AI algorithmic innovation, that capabilities have moved fast in recent years, and that Epoch will rerun the evaluation on later models.
For a team buying an AI product this week, the useful part is the number itself. One evaluation on two models produces a per-model run cost in low five figures and output a reviewer would decline. That is a figure a buyer can quote back when a vendor claims its agent will take research work off the team's roadmap.
Source
- Epoch AI, David Owen, Can AI automate AI R&D yet?
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.