Image: GitHub
Why it mattersA team that customises Copilot now has a built-in way to score the change. The old answer was to ask people on the team.
A team that writes a Copilot skill usually has no good way to score the next tweak. The same goes for an MCP tool. It is hard to tell if a change made Copilot better or worse. GitHub Copilot Evals is now in public preview. It answers that question inside the same tool.
GitHub announced the public preview in its Copilot changelog on 17 November. The company describes an eval as "a repeatable test for AI behavior." You give an agent a realistic task. You describe what a good result looks like. You check both the result and how the agent got there. The feature is free on Copilot Individual, Business and Enterprise.
What it does
Copilot Evals sits over three Copilot surfaces that teams already use. In VS Code it installs as an extension from the Visual Studio Marketplace. In the Copilot CLI it is a plugin from the public GitHub evals repository. In the GitHub Copilot app it is a marketplace plugin inside the Customize panel.
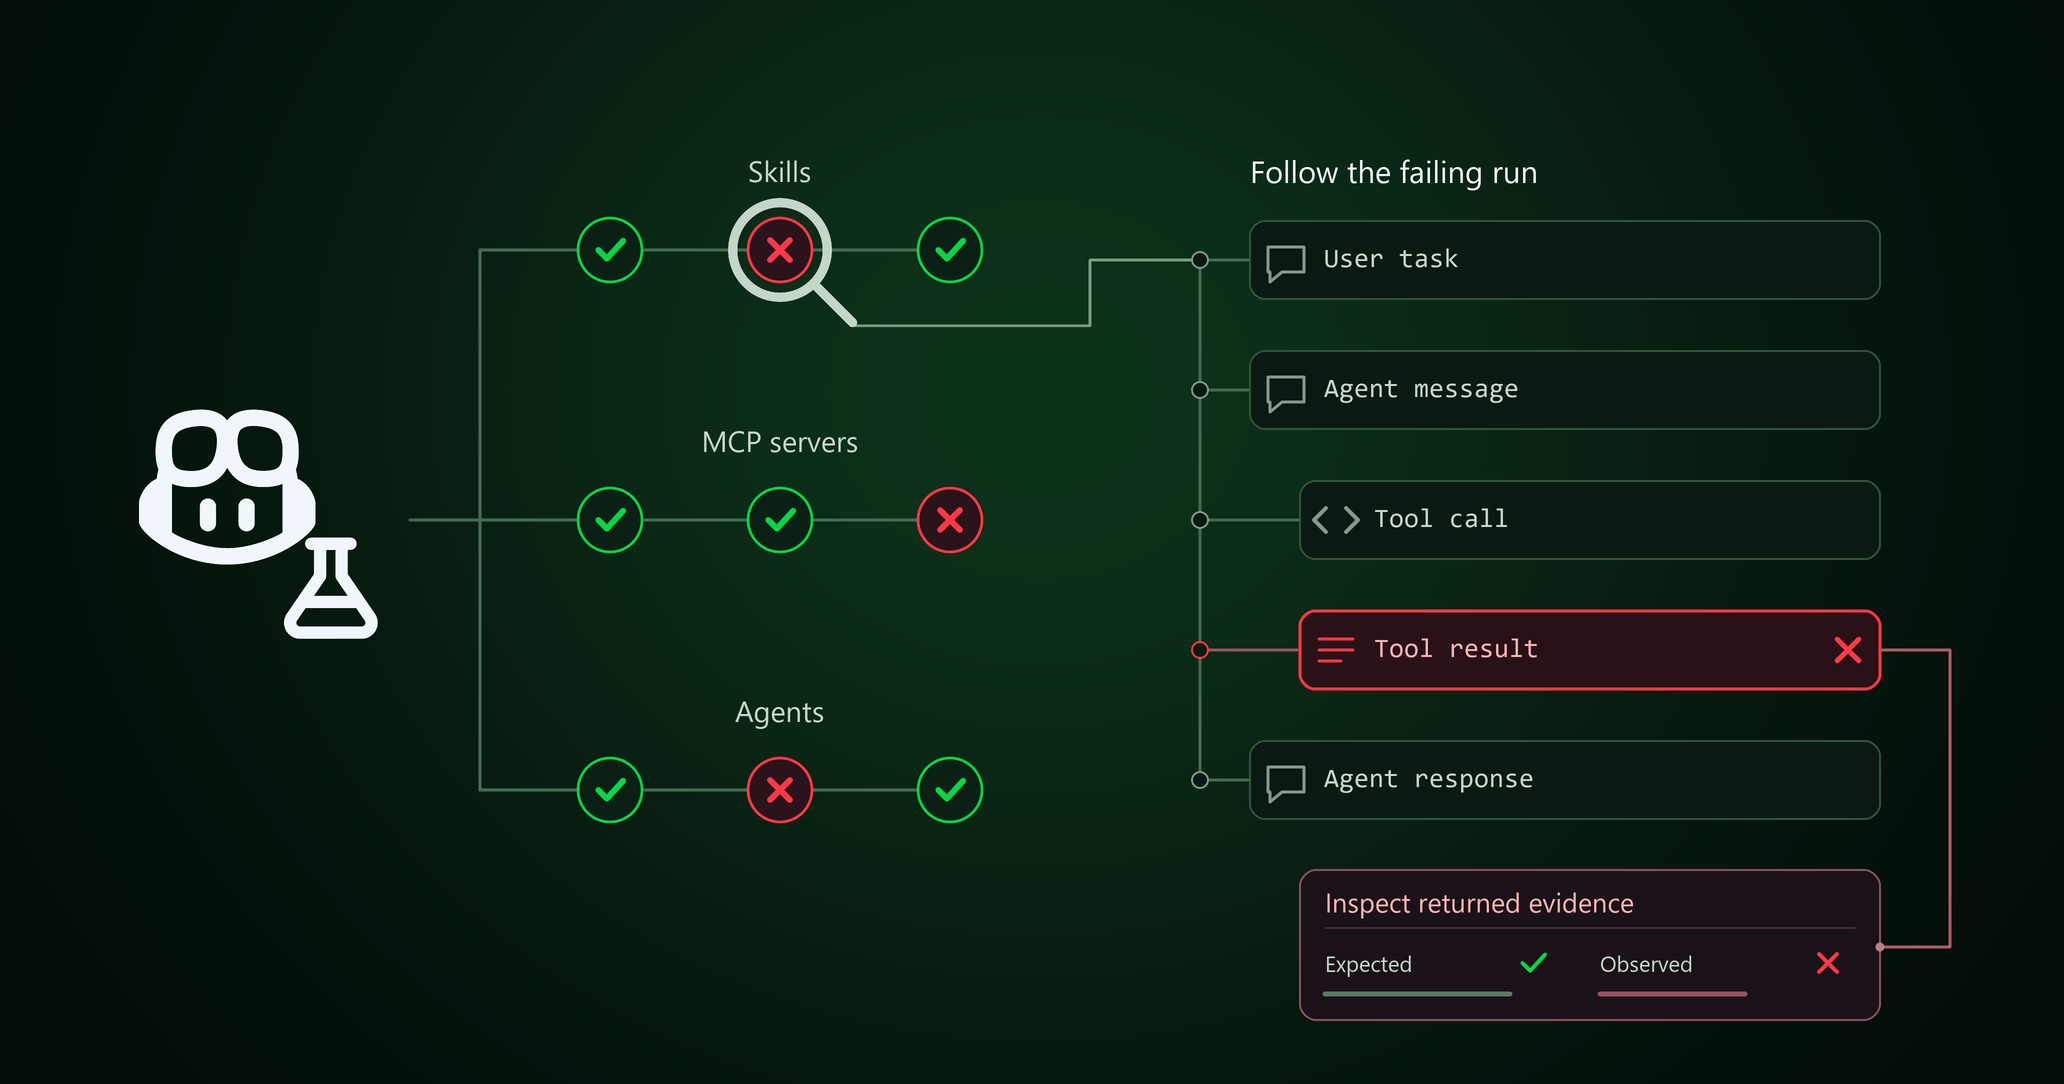
An eval defines a task, a success description, and the signals the grader should check. Copilot runs the task and reports which checks passed and failed. GitHub says the diagnostic view shows "steps" for a failed run. A reader can see which tool call or output broke the check. A before and after view compares two versions of the same prompt, skill or tool.
Where it fits in the stack
GitHub says Copilot Evals uses Vally as its evaluation engine. GitHub calls Vally "an extensible local eval tool." The grading runs on the developer's machine, not in a cloud service.
A team can score three things with it: skills, custom agents, and MCP tools. Those are the parts of Copilot a team writes itself. A skill tells Copilot how to answer a company question. A custom agent handles a long task. An MCP server lets Copilot read a private tool. None of those had a built-in grader before.
What is not in the post
GitHub did not state any pricing beyond listing the three plans. It did not say how the feature counts against the plan's token allowance, if at all. It did not publish a benchmark score against any other evaluation tool. Anyone comparing Copilot Evals to Vercel, LangSmith or Anthropic's internal verification is working from the product descriptions. One measured number is not available. GitHub also did not state whether Vally's output is portable to a different runner.
For a team on Copilot, this turns the next prompt tweak from a feeling into a scored test. The scored test is now in the same tool.
Source
GitHub Changelog: GitHub Copilot Evals is now in public preview.
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.

