AI NewsProductivityAnnouncement
Deepnote benchmarks 12 models on proactive help and when to stay quiet
Deepnote released the Agent Initiative Benchmark. It tests 12 frontier models on 50 workplace tasks inside a fictional company called PageMantle. The code and dataset are open.
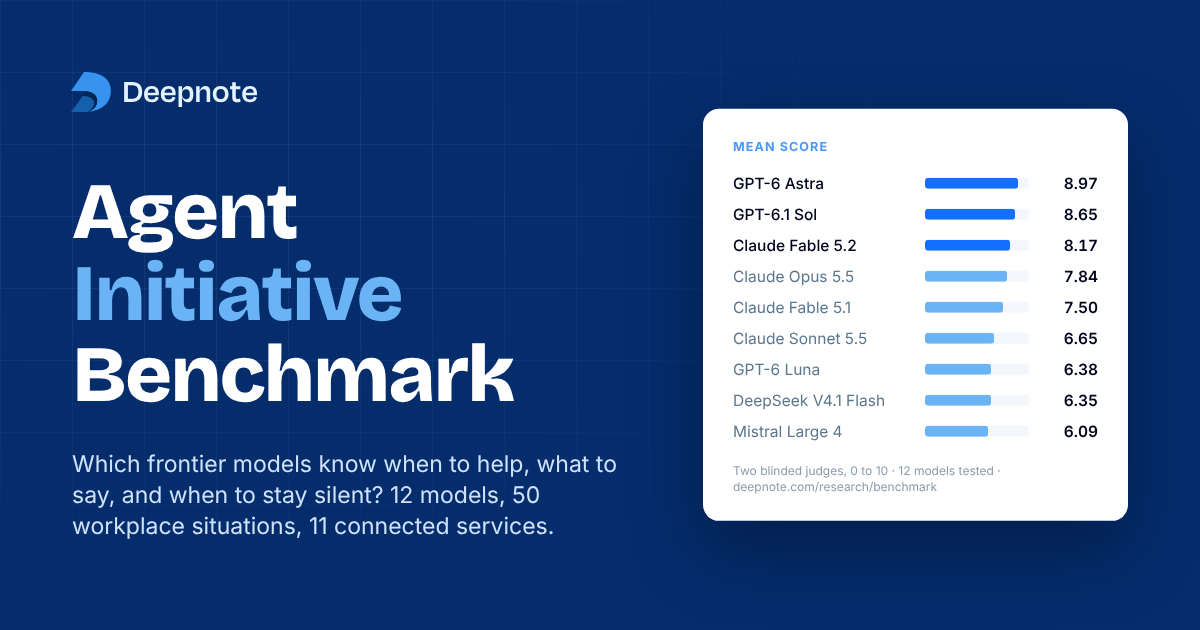
Image: Deepnote
Why it mattersA proactive agent now has a shared score for when it speaks and when it stays quiet. The benchmark names which models do each job at what cost.
A proactive AI agent is one that speaks up when it should. Teams building one have had no public measure of whether theirs does. Deepnote, a YC S19 company, released the Agent Initiative Benchmark. The code and the dataset come with it. Jakub Jurovych of Deepnote wrote the launch post.
The benchmark runs 12 frontier models through 50 workplace situations in eight task types: Find, Explain, Analyze, Verify, Diagnose, Decide, Coordinate and Guard. Each agent gets a 180 second budget per task. The setting is PageMantle, a fictional software company with six years of connected records across 11 services. Deepnote says it has 71 employees, 100 enterprise customers and 10 GB of data. The chat history is 9,000 Slack messages across 2,500 threads.
How the models placed
Deepnote scored each model from 0 to 10. GPT-6 Astra led at 8.97, followed by GPT-6.1 Sol at 8.65 and Claude Fable 5.2 at 8.17. Grok 4.7 came last at 4.51. Deepnote says Fable 5.1 costs 430 times more than GPT-6 Luna and scores only 1.1 points higher. By Deepnote's figures, the monthly cost to run one Slack load varied widely. It was 281 dollars on Sol and 4,684 dollars on Fable 5.2.
Two findings in the writeup. When a situation called for help, a message went out nine times out of ten across models. When the situation called for silence, a message was held back only six times out of ten. Grok 4.7 and Gemini 4 Argon averaged about 35 tool calls per task. The other models used 9 to 22. The figures are Deepnote's.
PageMantle runs on canned data
The code is at github.com/deepnote/agent-initiative-benchmark under Apache 2.0. The dataset, PageMantle, is on Hugging Face under CC BY 4.0. Deepnote describes PageMantle as a self-contained local fixture: the services run on canned data so a team can score an agent without touching a live account.
Reveneau builds evals for AI products from the specification. A change only reaches production after the suite passes. A shared, open scoring job for proactive behaviour removes a step teams invent each time. It also gives a buyer a second opinion when a vendor states a score on its own benchmark. The limits are on the page. There are 12 models, one synthetic company and one grader. A team adopting it will want its own tasks beside PageMantle's. It will want its own graders beside Deepnote's too.
Source
Agent Initiative Benchmark, Deepnote. Launch post on Y Combinator. Code on GitHub.
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually using them to release software. Short, and only when there is something worth reading.