Irakli Betchvaia shows a Kotlin-embedded DSL cuts model hallucinations, with a curated examples tool lifting first-compile from 25 to 87.5 percent
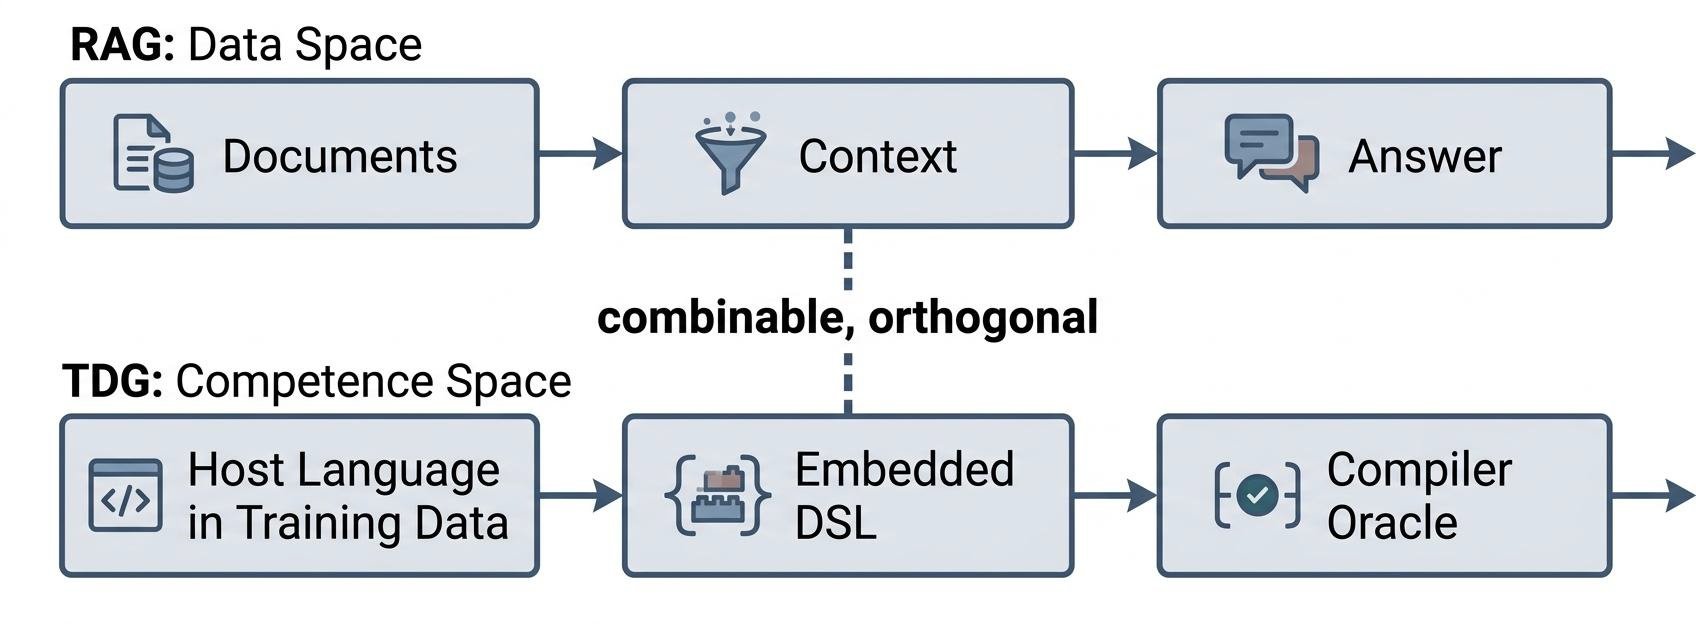
Image: Irakli Betchvaia, via InfoQ
Why it mattersTeams that give coding agents a custom notation get invented syntax with confident tone; putting the DSL inside Kotlin or TypeScript turns those inventions into compile errors the agent can see and repair.
In an InfoQ article published on 16 September, Irakli Betchvaia introduces Typed Domain Grounding, a design pattern for domain-specific languages that are read and written by language models. The claim is that a home-grown DSL, embedded inside a mainstream typed host language, turns model hallucinations that a lenient renderer would silently accept into compile errors the model can see and fix. Betchvaia backs it with a fifty-task benchmark on kUML, a Kotlin-embedded modeling language for UML, SysML v2, and C4 diagrams.
Where retrieval falls short
Betchvaia argues that retrieval-augmented generation grounds the content of a response but does nothing for the notation used to express it. A model can have correct facts in context and still emit a DSL statement with invented keywords, guessed parameter names, and constructs that were never in the specification. He calls this a training-corpus-frequency problem: mainstream languages appear in millions of public files, and a freshly designed external DSL appears in none. The reflexive fixes of more prompting, longer context, and better retrieval do not address the gap.
The alternative rule, in Betchvaia's own sentence: never invent syntax a model has never seen. Embed the domain in a language it already writes fluently, and let the compiler be the oracle.
The five design commitments
The article describes five parts. The DSL is embedded rather than external, so it inherits highlighting, completion, refactoring, and reviewer-familiar diffs from the host toolchain on day zero. The host language is picked by training-data affinity, which Betchvaia says pulls toward Kotlin, TypeScript, or Python for most domains. The API is shaped so that domain errors surface as type errors, using named parameters, enums instead of strings, sealed hierarchies, and receiver-scoped builders. A generate-compile-repair loop feeds the compiler diagnostic back to the model as a targeted repair prompt, bounded at three attempts in the kUML setup. An on-demand teaching channel, exposed as a tool the model can query mid-generation, returns a small set of known-good compiling examples for the exact construct the model needs.
The measured effect
Betchvaia reports that on a fifty-task benchmark with Claude Sonnet 5, kUML reached higher Structural Fidelity and a lower hallucination rate than two lenient external DSLs, despite a lower first-try compile rate. He says the same pattern held for GPT-4o, and adds that it does not hold for every model tested, so a strict rejecting oracle can converge to more reliable output than a forgiving one but is not guaranteed to. The most concrete number in the article is on the teaching channel: for kUML, exposing a curated examples tool raised the first-compile rate for SysML v2 diagrams from 25 percent to 87.5 percent.
Trades are stated plainly. TDG closes syntax gaps; understanding gaps stay open. It gives up notational freedom, and it commits the project to a host language. Betchvaia frames it as a default consideration for new DSLs, and stops short of a mandate to rewrite ones that already work.
For a team giving a coding agent its own notation, the argument is that the compiler is a cheaper and more reliable reviewer than a prompt, and that the fix belongs in the language design itself.
Source
Your Next DSL Author Is a Language Model, by Irakli Betchvaia on InfoQ.
Reported by: InfoQ
This item was written by an AI system from the linked source. Reveneau is responsible for what it publishes.
Get AI News in your inbox
New developer tools, model and agent releases, and how teams are actually shipping with them. Short, and only when there is something worth reading.